Seedance 2.5 vs MiniMax H3
Two AI video models, one Topview workspace. Compare duration, resolution, multimodal references, native audio, and open vs hosted access — then pick the model that fits your project.
Side by Side
Same Prompt, Two Models
For each brief below, the same prompt and reference inputs (when used) are run through Seedance 2.5 and MiniMax H3 — no re-rolls. Watch both outputs and judge for yourself.
VFX Spectacle Comparison
Text Only
Prompt
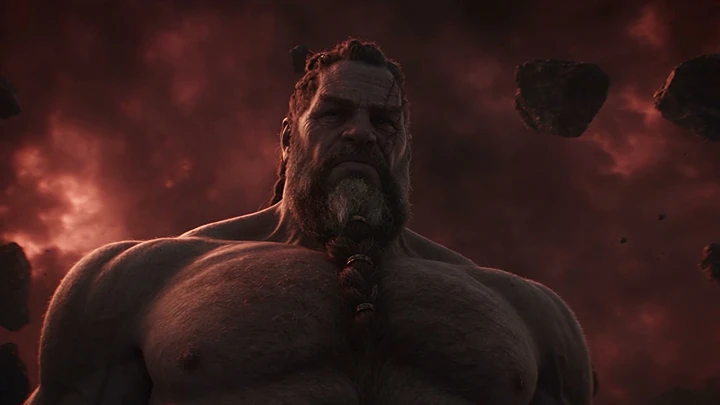
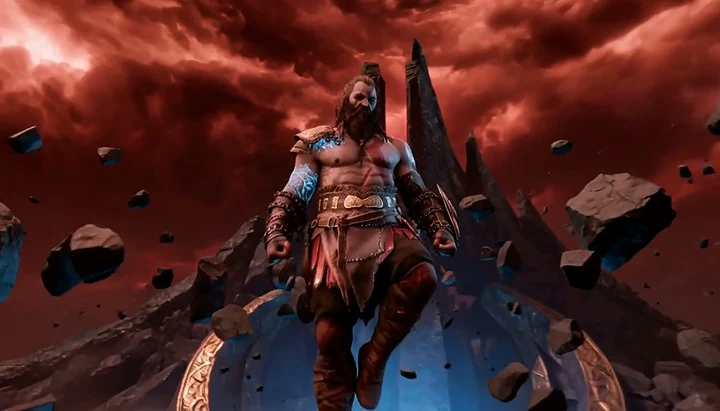
Dialogue Scene Comparison
3 Images
Image Ref 1
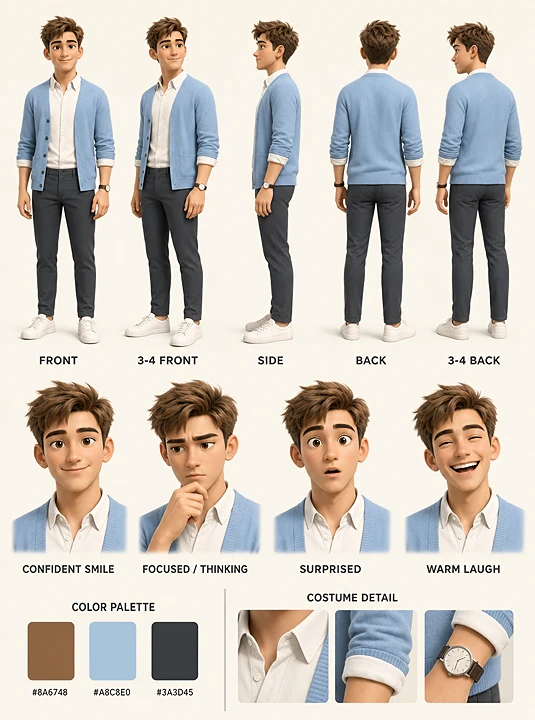
Image Ref 2
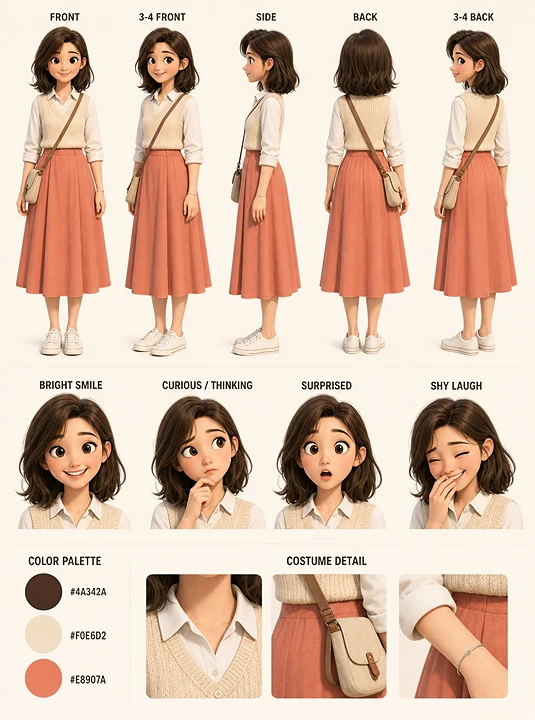
Image Ref 3
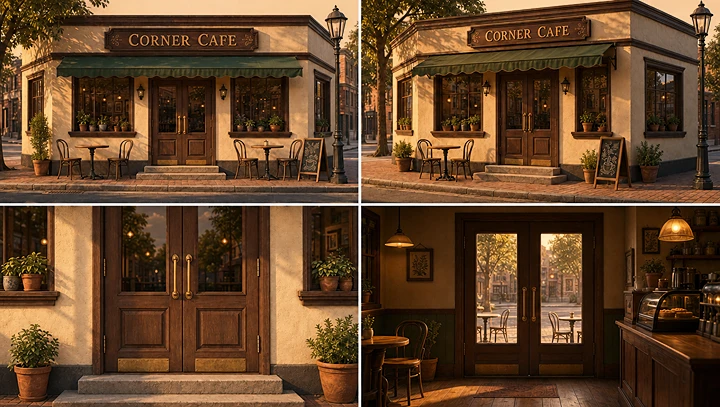
Prompt
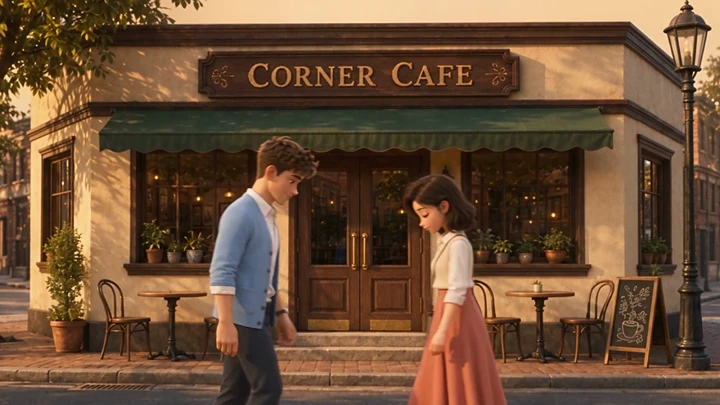
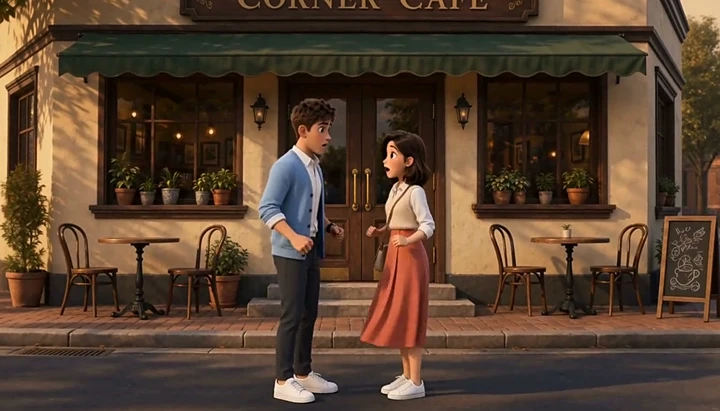
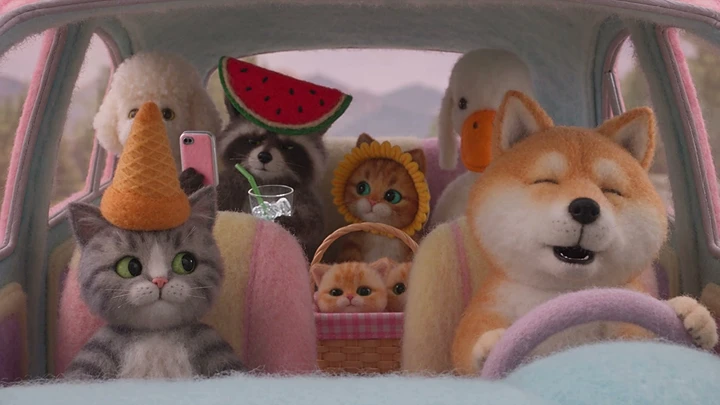
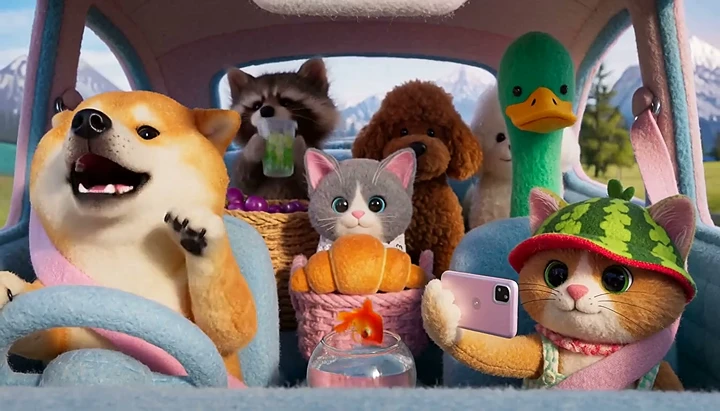
Ensemble Acting Comparison
Text Only
Prompt
Group Dance & Beat Sync Comparison
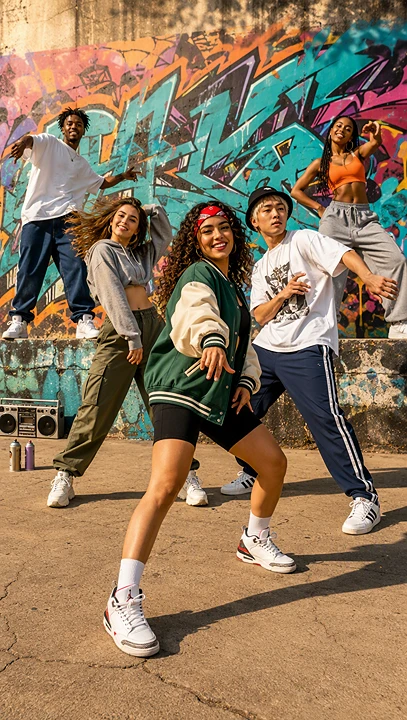
1 Image + Audio
Image Ref 1
Audio Ref
Beat track reference
Prompt
Literature Adaptation Comparison
Text Only
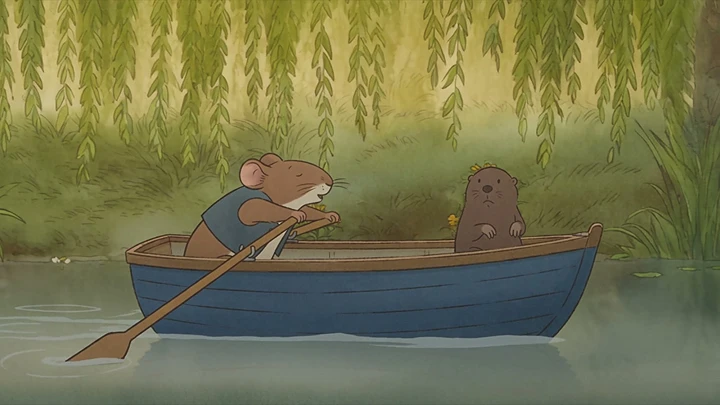
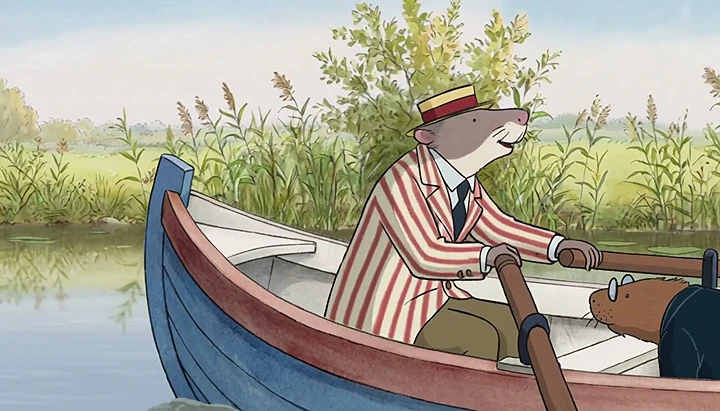
Faithfully adapted from The Wind in the Willows (1908), Ch. I — judge each model against the original passage shown alongside.
Prompt
Original Passage
"Believe me, my young friend, there is nothing—absolute nothing—half so much worth doing as simply messing about in boats. Simply messing," he went on dreamily: "messing—about—in—boats; messing—" "Look ahead, Rat!" cried the Mole suddenly. It was too late. The boat struck the bank full tilt. The dreamer, the joyous oarsman, lay on his back at the bottom of the boat, his heels in the air. "—about in boats—or with boats," the Rat went on composedly, picking himself up with a pleasant laugh." — Kenneth Grahame, The Wind in the Willows (1908), Chapter I, Project Gutenberg #27805 (Scribner 1913 ed.)
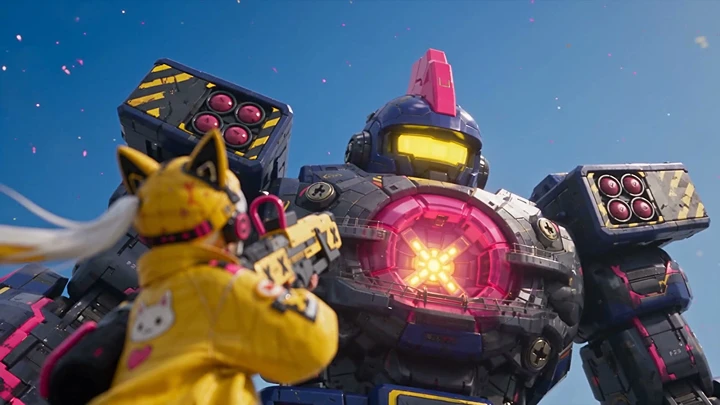
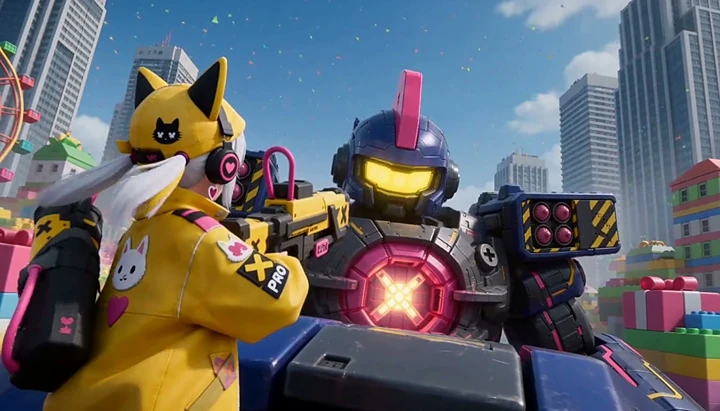
Game Boss Battle Comparison
2 Images
Image Ref 1
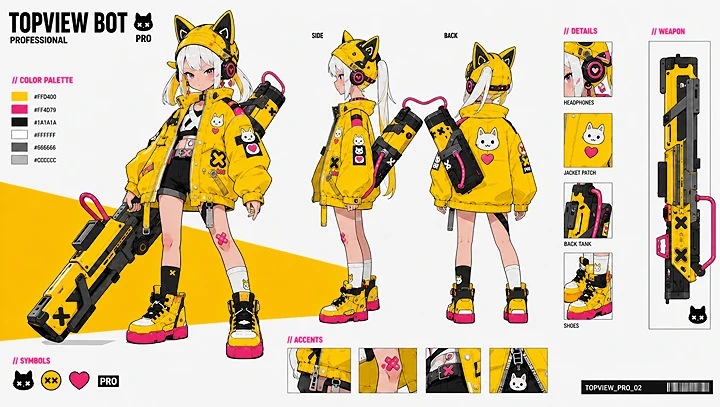
Image Ref 2
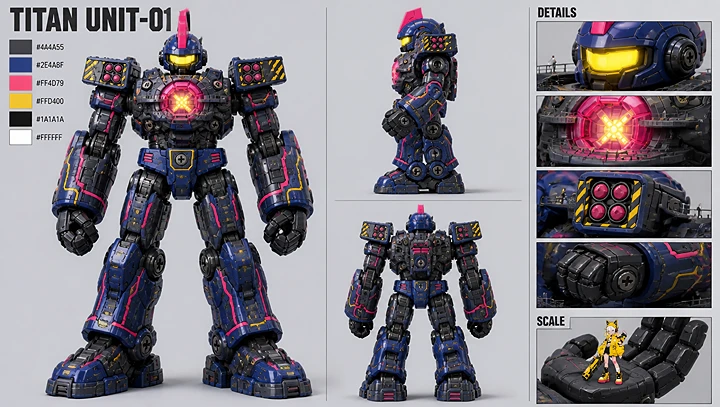
Prompt
Spec-by-Spec Comparison
Each value reflects how the model is represented on Topview and each vendor's publicly available information — no benchmark scores or blind-test claims, just the facts side by side.
| Dimension | Seedance 2.5 | MiniMax H3 |
|---|---|---|
| Developer | ByteDance | MiniMax |
| Model Type | Multimodal video model (hosted) | Omni-Modality Transformer (open weights) |
| Deployment & Access | Hosted on Topview (and ByteDance / partner platforms) | Open weights; API / open platform; private / on-prem ready |
| Resolution (Topview) | 480p / 720p / 1080p | 768p / Native 2K (2560×1440) |
| Duration | 4s–30s native continuous clip | 5s–15s per shot |
| Image Inputs | Up to 30 images | Up to 9 (max 15 combined across refs) |
| Video Inputs | Up to 10 clips (combined ref video ≤30s) | Up to 3 clips (max 15 combined across refs) |
| Audio Inputs | Up to 10 files (combined ref audio ≤30s) | Up to 3 files (max 15 combined across refs) |
| Total References | Up to 50 assets | Up to 15 combined |
| Native Audio | Dialogue, music, SFX with time-coded direction | Dialogue + music + lip-sync |
| Multilingual Lip-sync | Multilingual dialogue; more reliable subtitle handling (as on Topview) | Global multilingual lip-sync |
| Best For | Longer continuous stories, heavy multimodal refs (50 combined), auto duration | 2K visuals, open / private deploy, omni-modal editing |
Spec values above follow Topview production generator config for Seedance 2.5 and MiniMax H3 (selectable resolution tiers and reference limits). Third-party 4K-as-default-output, Elo, or price claims are excluded. No win/loss benchmark claims are made.
Where Each Model Stands Out
Seedance 2.5
Longer Continuous Clips
Generate a coherent 4–30 second sequence in one pass — more room for ads, explainers, and multi-beat stories without stitching many short fragments.
Heavy Multimodal Control
Guide identity, motion, and sound with up to 50 references (30 images, 10 videos, 10 audio) plus internet-search-grounded prompts.
Production-Style Editing
Revise a selected segment of a 4–30s clip without regenerating the whole take — built for iterative production.
MiniMax H3
Native 2K Output
Generate at native 2K (2560×1440) for sharper product and commercial frames when resolution is the priority.
Open Weights & Private Deploy
Self-host, fine-tune, or run on-prem when data residency or stack control rules out a pure hosted API.
Omni-Modal Editing
Combine text, image, audio, and video guidance with native dialogue, music, and lip-sync for fast multimodal iteration.
Which Model Fits Your Workflow?
Match your project to the model built for it.
Longer continuous ad or explainer up to 30 seconds
Native 4–30s generation gives a complete idea room to establish, develop, and resolve in one clip.
Letting the model auto-adjust clip length to match pacing
Auto-duration is flagged for Seedance 2.5 on Topview, picking an appropriate length within the 4–30s range without manual trimming.
Maximum reference count across image, video, and audio
Up to 50 multimodal assets support complex brand and world-building packages.
Native 2K product or commercial frames
Native 2K output is positioned for sharper deliverables when resolution leads the brief.
Private / on-prem or open-weight pipeline
Open weights and private deployment fit teams that cannot rely only on a hosted cloud API.
Fast multimodal clips with native lip-sync
Dialogue, music, and lip-sync in one omni-modal pass suit short social and localization tests.
Local segment revision after a strong base clip
Local editing keeps the rest of the sequence more stable while you revise a selected beat.
Instruction-led omni-modal rewrite (voice, tone, scene)
Omni-modal editing is positioned for voice/tone transfer and scene rewrite workflows.
Frequently Asked Questions
Try Both Models on Topview
Same workspace, same references — pick the model that fits the brief, or run the idea through both.